

Quick to
Find structure prediction tools
On All Tools, open the Function filter (1) and check Structure Prediction (2). The filter appears as a chip (3). Click Clear all to remove it.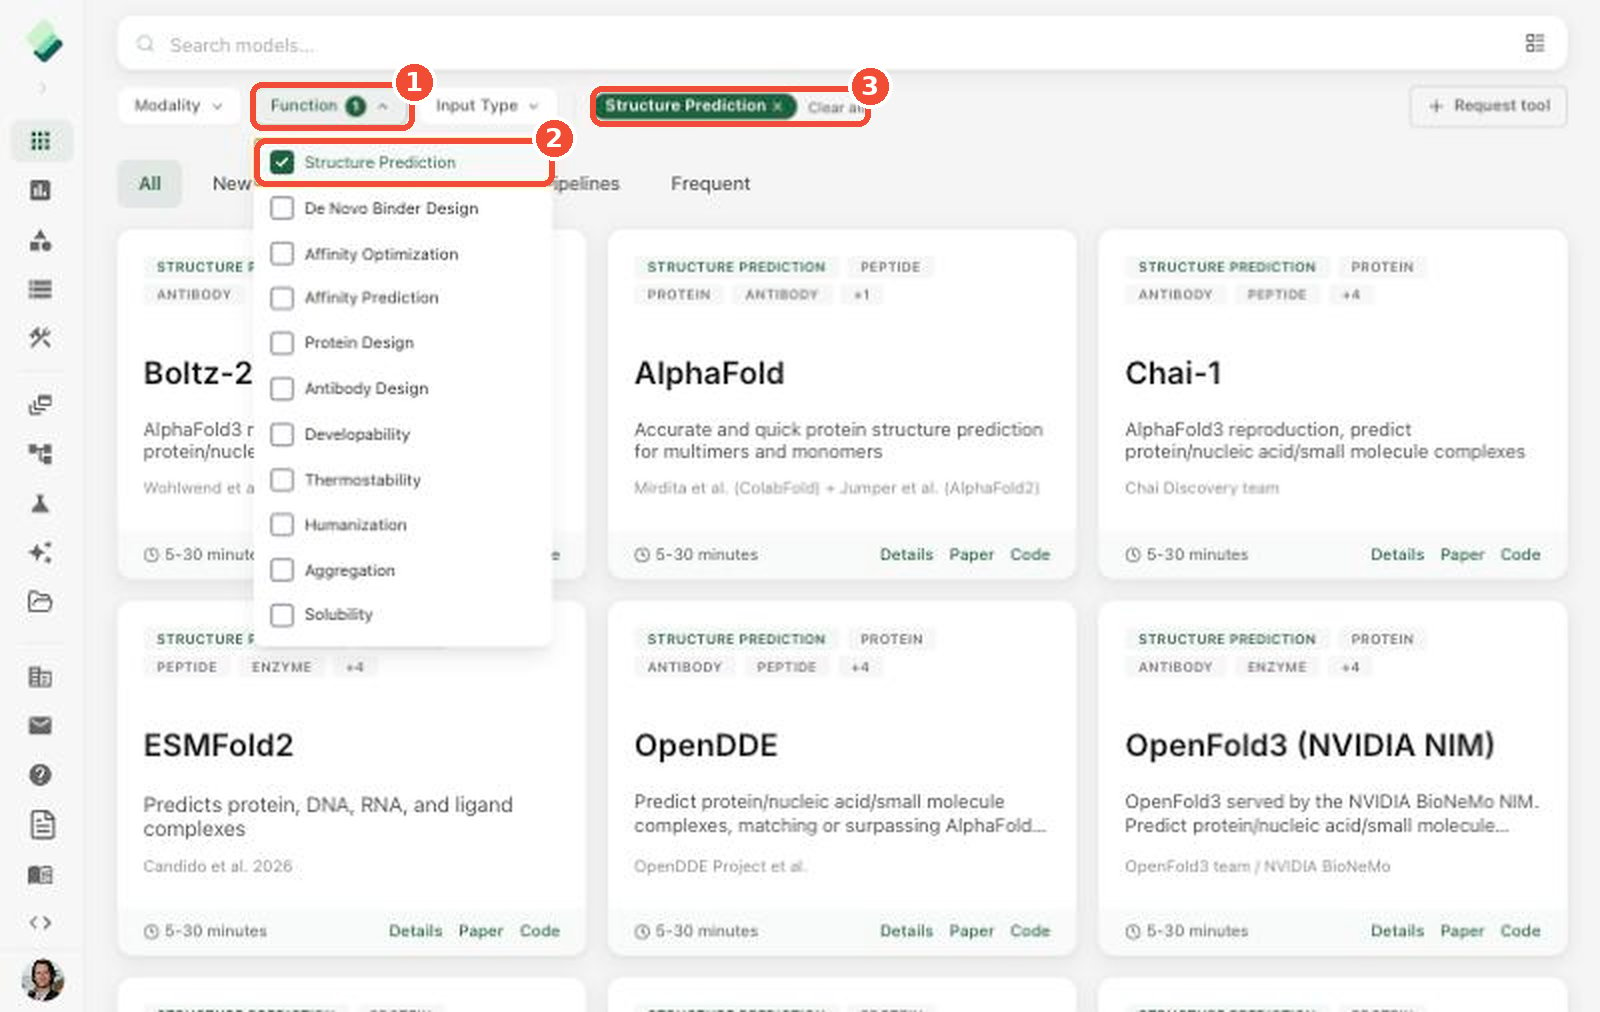
Recommended tools
For most proteins and complexes, start with one of these. AlphaFold3-class models (all-atom co-folding) can include proteins, nucleic acids, small molecules, and ions in the same prediction.About these models:
- Boltz-2 (MIT and Recursion, 2025) predicts structure and binding affinity together. Its developers report affinity accuracy approaching physics-based free energy methods at a fraction of the time and cost (Bio-IT World). It is released under the MIT license.
- OpenFold3 was released by the OpenFold consortium in October 2025 under the Apache 2.0 license, and is available hosted on Tamarind (Business Wire).
- Protenix is ByteDance’s open AlphaFold3 reproduction (bioRxiv).
Tools for specific cases
Conformations and experimental data
AFSample2 uses AlphaFold’s jackhmmer MSAs instead of MMseqs2, so runs can take several hours.
Multiple sequence alignment (MSA)
An MSA collects sequences related to your input from large databases. The evolutionary information it captures helps models predict the structure. The result is an.a3m file that’s passed to the model.
- On by default. MSAs are generated automatically for structure prediction tools.
- Turning it off. AlphaFold2 and Chai-1 let you disable MSAs. For Boltz-2, you can get a similar effect by limiting the MSA depth to one sequence.
- How Tamarind builds MSAs. Tamarind uses the ColabFold MMseqs2 method to search UniRef30, BFD, and the ColabFold environmental database. Tamarind runs its own MSA servers with the databases loaded into memory, which makes MSA generation much faster.
Confidence metrics
Every prediction comes with confidence scores. Use them to decide which models to trust.pTM is less useful for very small structures, and large disordered regions lower pTM and ipTM. A complex can still be predicted correctly with lower values if PAE between the ordered parts is low (EMBL-EBI).
Input limits and speed
Each tool page shows an Estimated Runtime and Est. Compute Cost before you submit. See Compute Hours.
AlphaFold2
AlphaFold2 moved the field from physics-based modeling to deep learning, using attention-based networks and evolutionary information from MSAs. Its training data cutoff is April 30, 2018, which is useful to know when benchmarking. Settings:- Models: AlphaFold2 has 5 sets of weights, so it returns up to 5 models, ranked with the best first.
- Recycles: 3 by default, up to 20. By default, recycling stops early if the structure barely changes. Turn on No Stop to always run every recycle.
- Relaxation: Uses ColabFold’s AMBER relaxation. For further energy minimization, use Tamarind’s OpenMM molecular dynamics tool.
AlphaFold3-class models
AlphaFold3 itself is not available for commercial use. Tamarind offers open models that reproduce or exceed its accuracy, including Boltz-2, Chai-1, Protenix-v2, OpenFold3, IntelliFold 2, and RosettaFold-3.- All-atom. These models can include small molecules, nucleic acids, ions, and modified residues.
- Generative. Each run can produce many samples. To find a specific pose, generate more samples, then pick by confidence score or by clustering.
- Ranking. The overall confidence score is the most useful metric for ranking samples.
Antibodies
- With the antigen: Use Boltz-2, Chai-1, or Protenix-v2. If you know the epitope or paratope, add restraints and generate many samples.
- Without the antigen: ImmuneBuilder, ABodyBuilder3, and FlashABB are very fast and give reasonable structures for large numbers of antibodies or nanobodies.
- TCRs: Use TCRModel2 for class I, class II, and unbound TCRs.
Peptides
- Boltz-2 and Chai-1 perform best for peptide–protein complexes. Try both and choose the one that best matches your data.
- For cyclic peptides, use Boltz-2 and check Cyclic on the peptide chain, or use Highfold.
Linkers
Model linkers as part of the chain. For example, to join two proteins with a flexible linker, include the linker in the sequence and predict it as one chain with any tool:Example workflow: protein–ligand complex with binding affinity
This walkthrough uses Boltz-2’s built-in example to predict a protein bound to a small molecule and estimate binding affinity.1. Open Boltz-2
Go to Boltz-2, or click the Boltz-2 card on All Tools.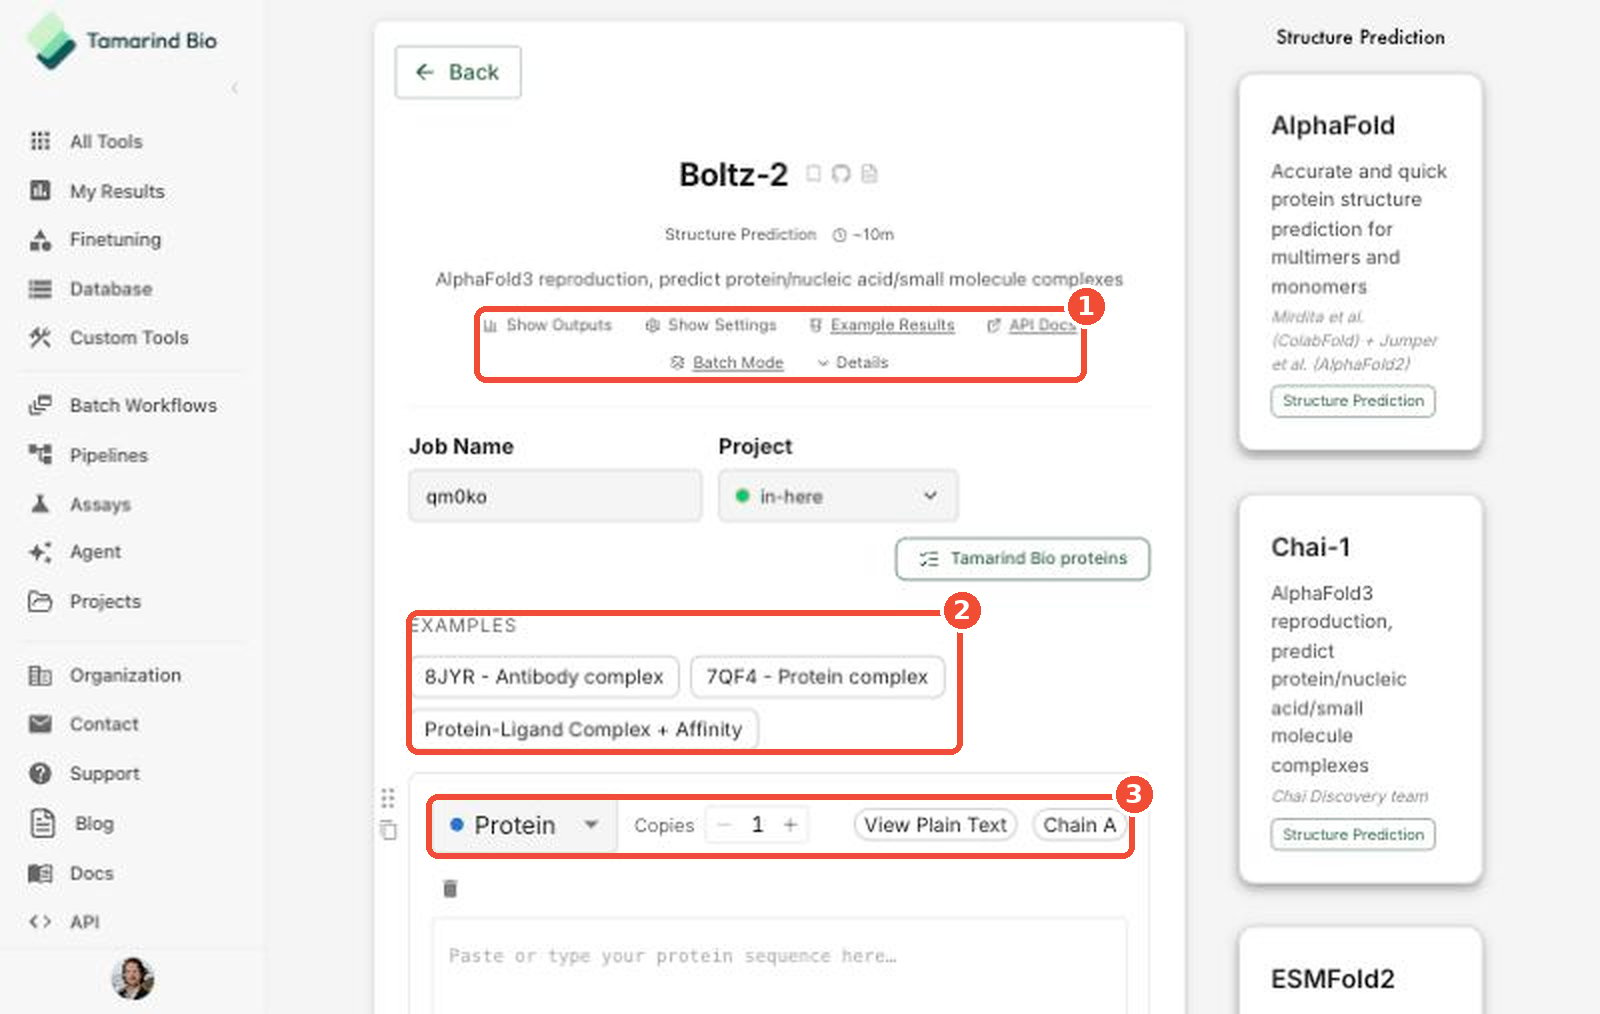
- Tool info — Show Outputs, Show Settings, Example Results, API Docs, Batch Mode, and Details. Click Example Results to see a finished example without running anything.
- Examples — load a ready-made input: 8JYR – Antibody complex, 7QF4 – Protein complex, or Protein-Ligand Complex + Affinity.
- Chains — each chain has a type (such as Protein or Ligand), a number of Copies, and a chain ID.
2. Check the protein chain
Chain A is filled in with a 384-residue protein sequence (1). To use your own protein, paste a sequence, click Import FASTA, or choose from Tamarind Bio proteins.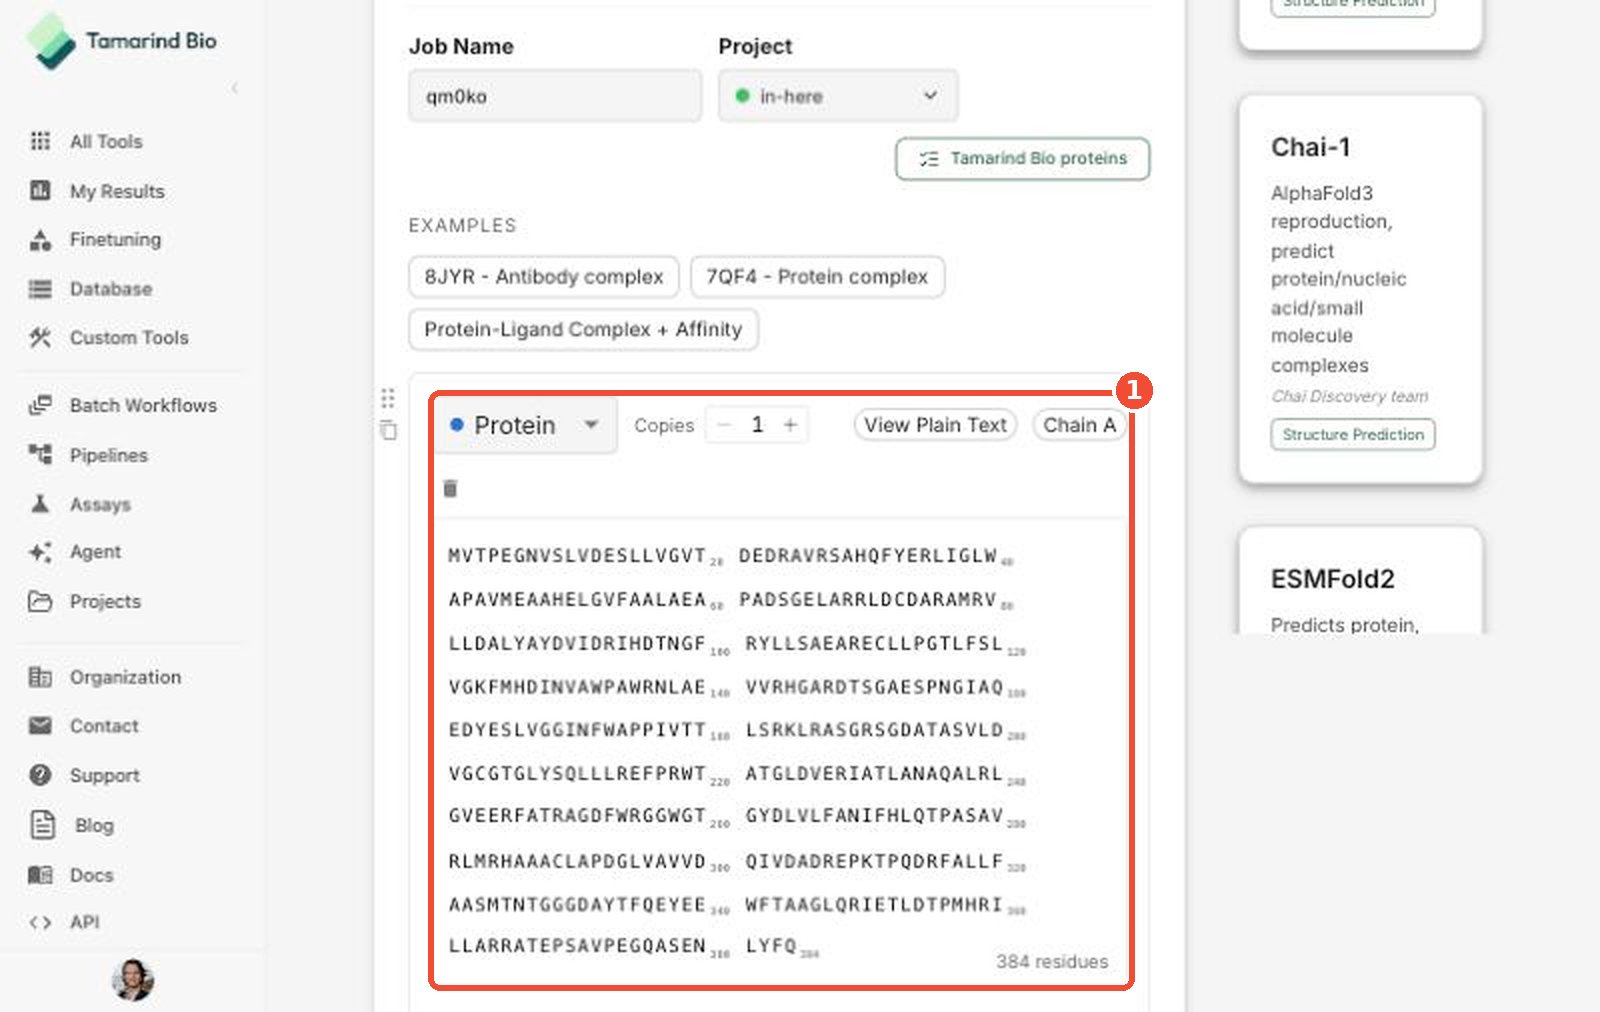
3. Check the ligand
Chain B is a Ligand (1). Enter it as a SMILES string or a CCD code (2) (use CCD codes for ions). A 2D drawing of the molecule appears below. You can also pick from Tamarind Bio compounds.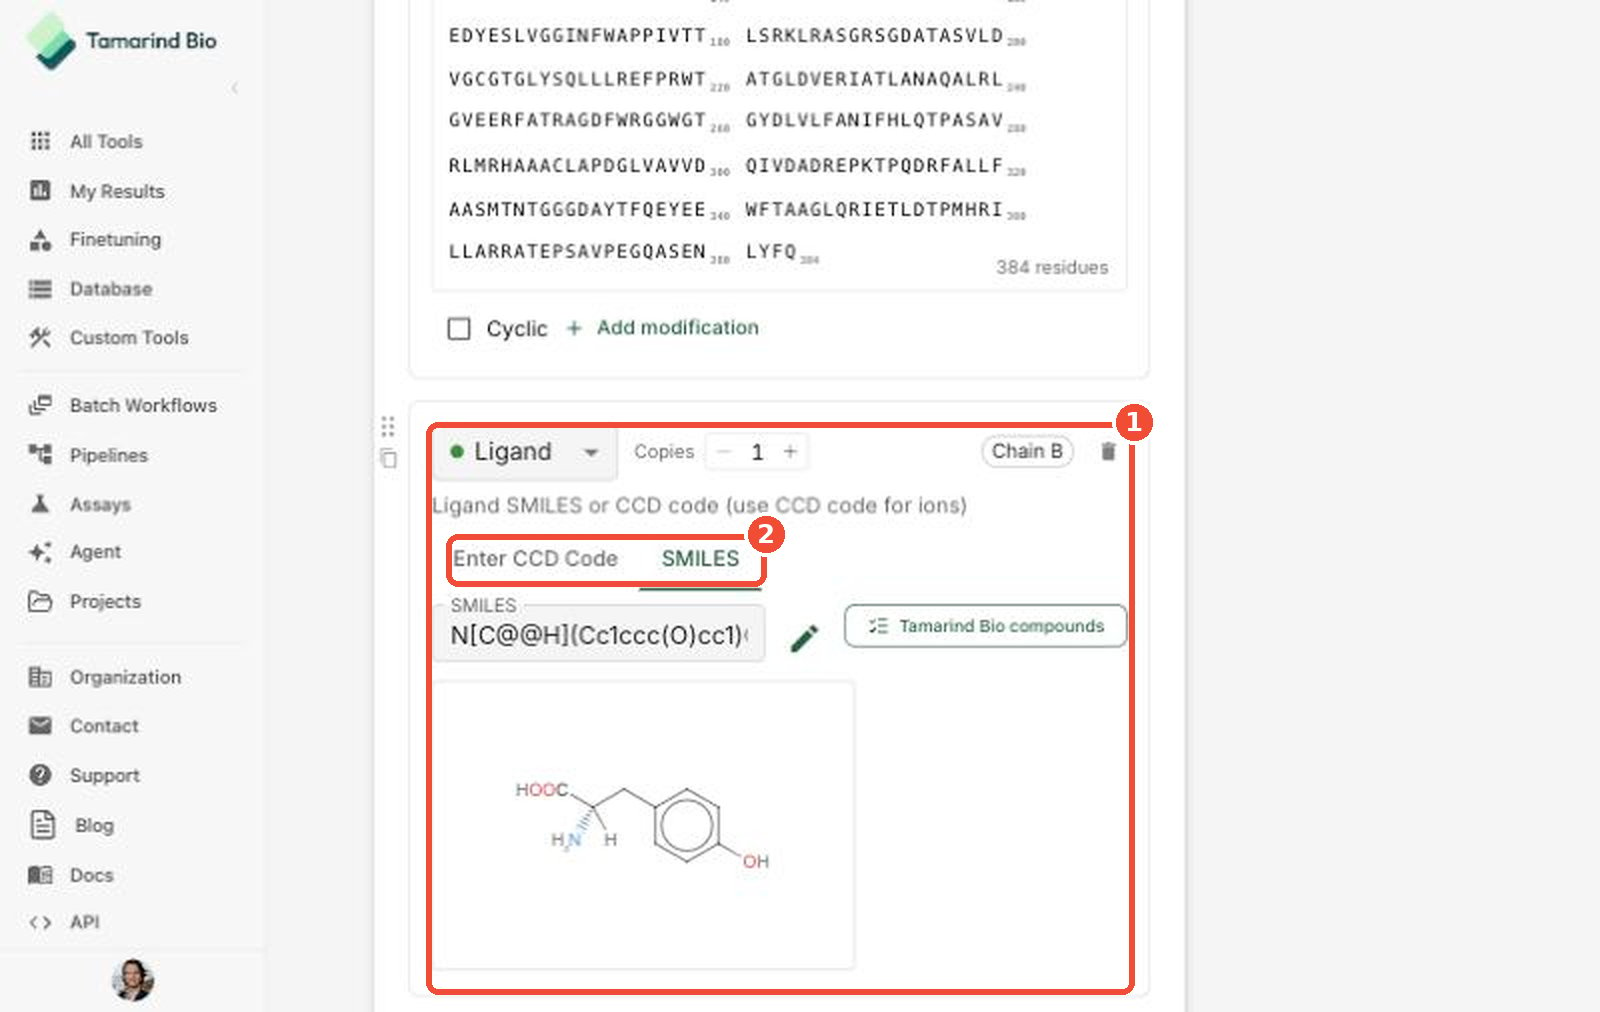
4. Add a restraint (optional)
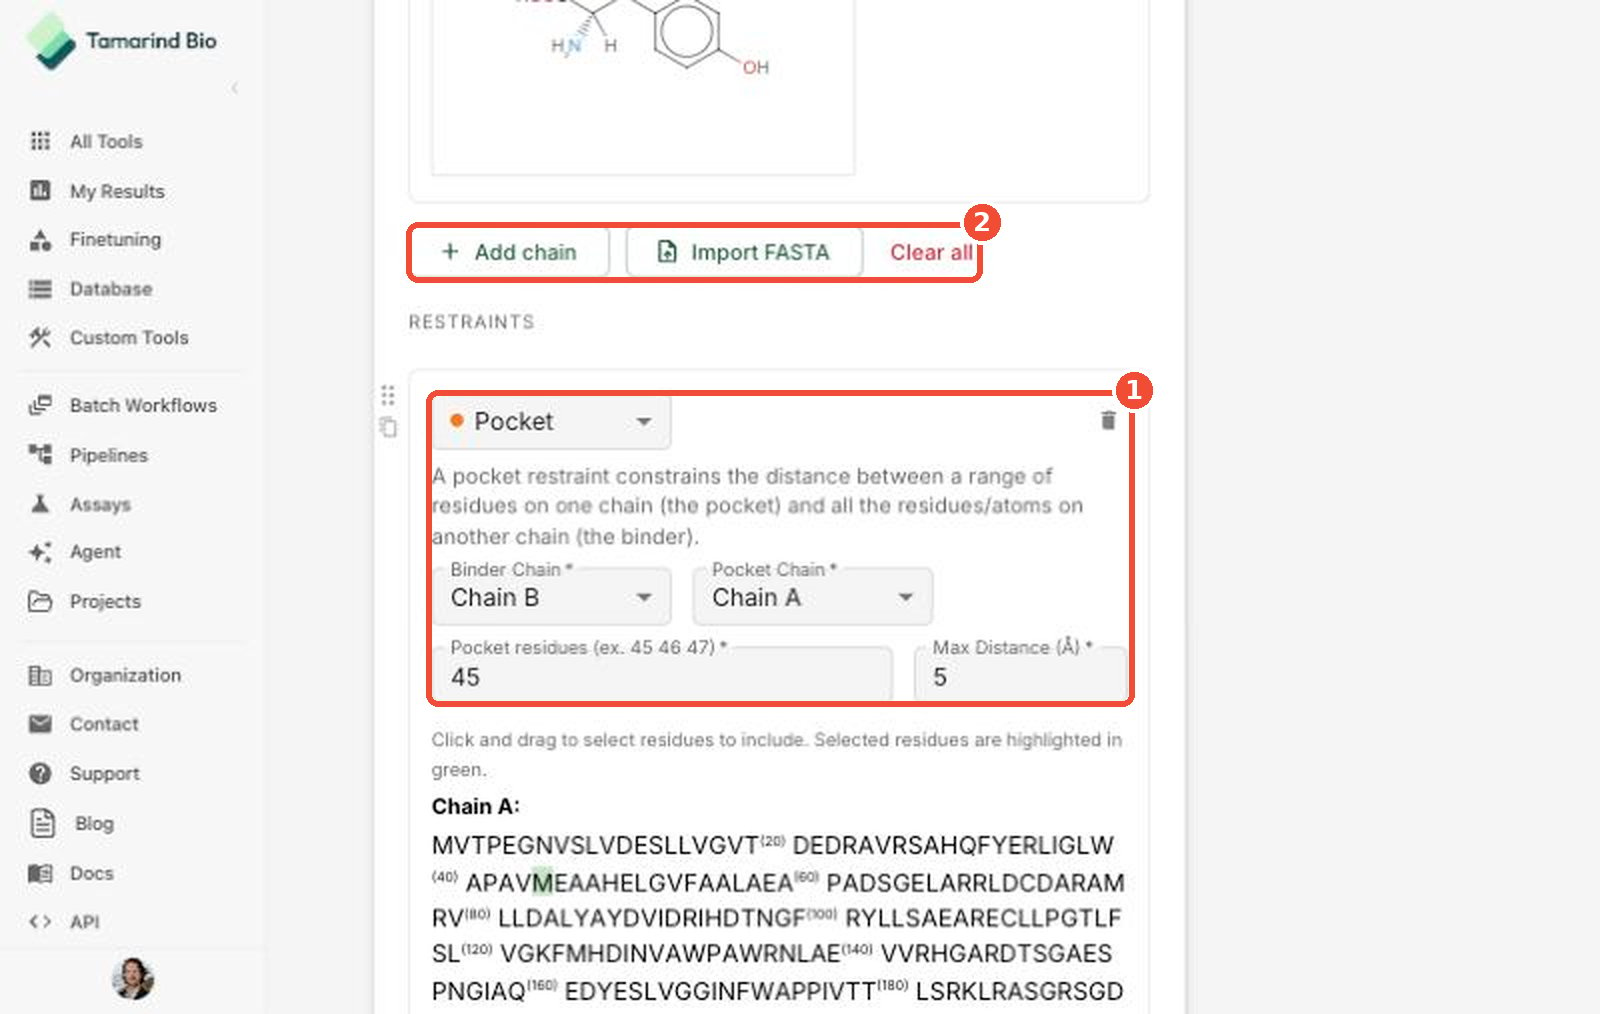
If you know where the ligand binds, add a restraint (1). The example uses a Pocket restraint:- Binder Chain: Chain B (the ligand)
- Pocket Chain: Chain A (the protein)
- Pocket residues:
45 - Max Distance (Å):
5
5. Turn on affinity and set samples
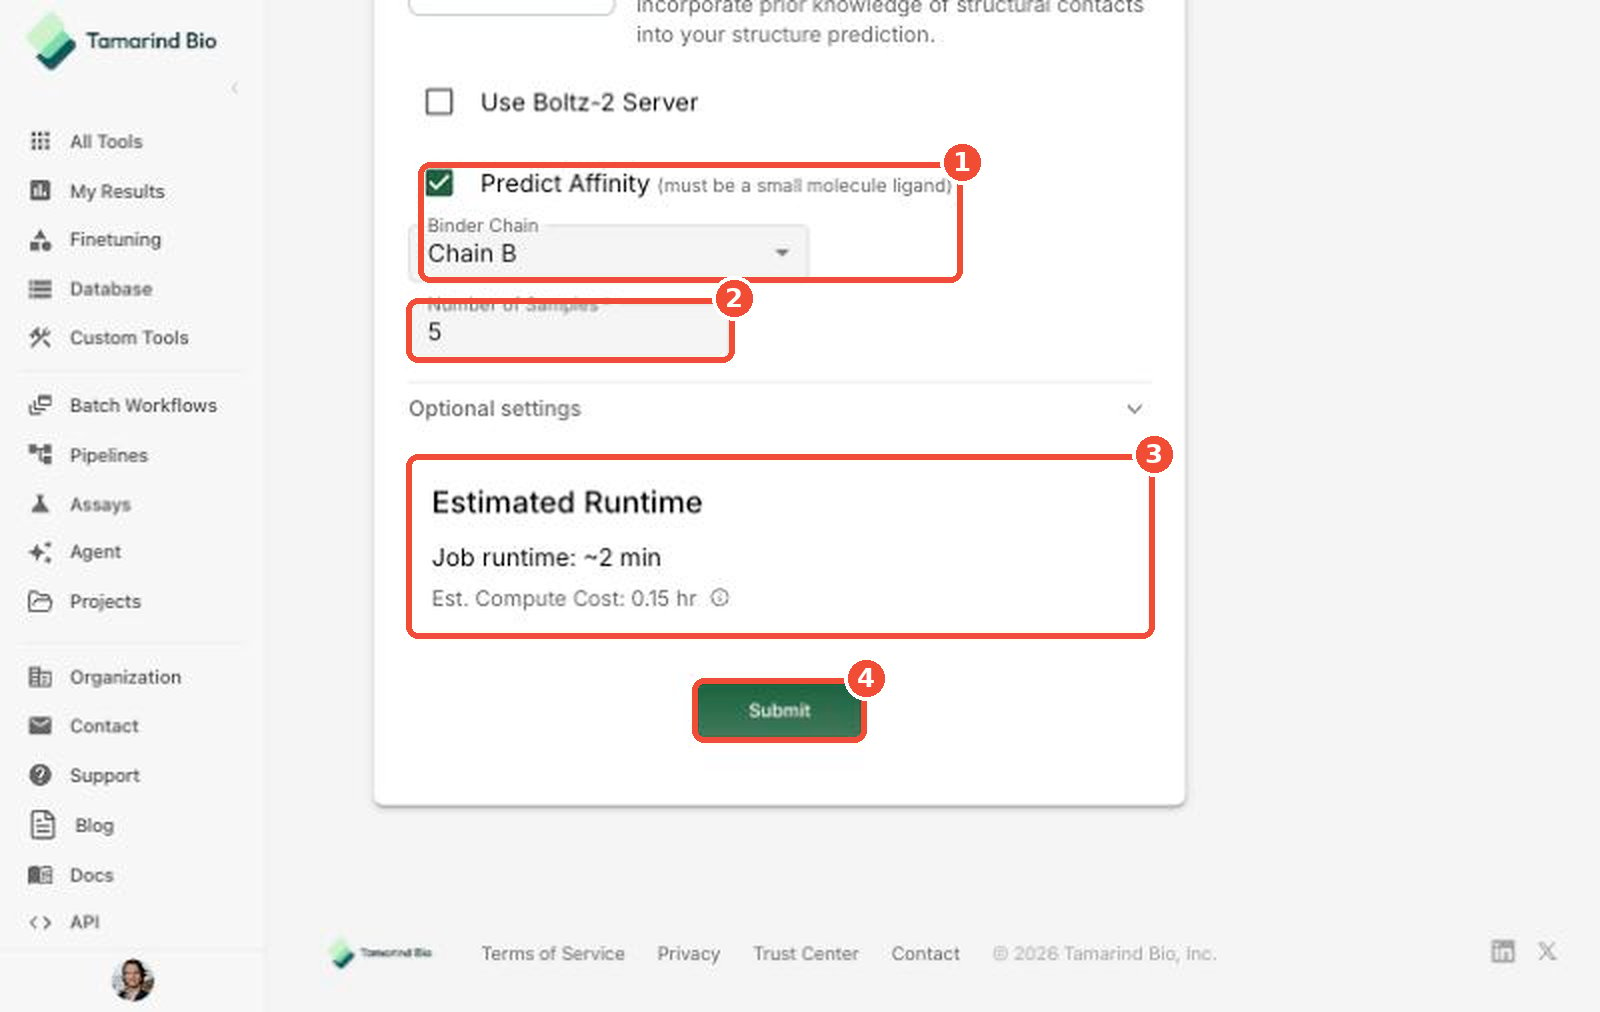
- Check Predict Affinity and set the Binder Chain to the ligand (Chain B). Affinity prediction only works for small-molecule ligands.
- Set Number of Samples (the example uses 5). More samples give more chances to find the right pose but take longer.
- Check Estimated Runtime and Est. Compute Cost (about 2 minutes and 0.15 weighted hours for this example).
- Click Submit.
6. Read your results
Open the job from My Results (or click Example Results on the tool page to see this example’s output).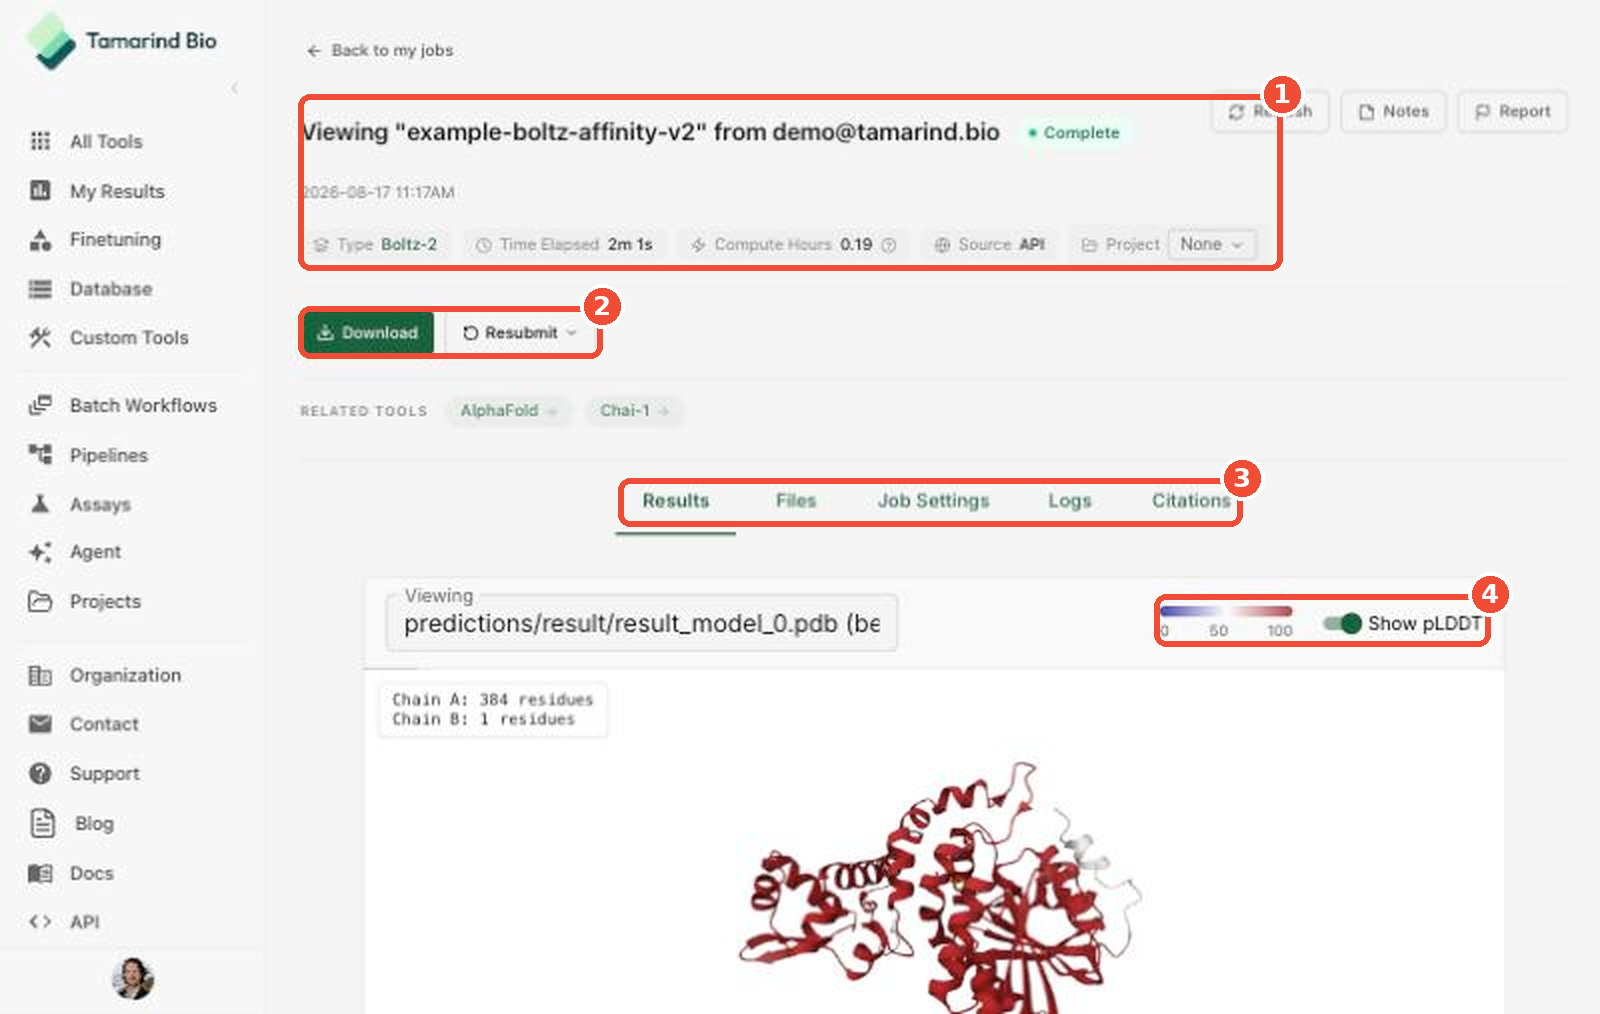
- Job summary — status, tool, time elapsed, compute hours used, source (app or API), and project.
- Download / Resubmit — download all outputs, or resubmit with the same or changed settings.
- Tabs — Results, Files, Job Settings, Logs, and Citations.
- 3D viewer — choose a model file and turn on Show pLDDT to color the structure by confidence (blue is low, red is high).
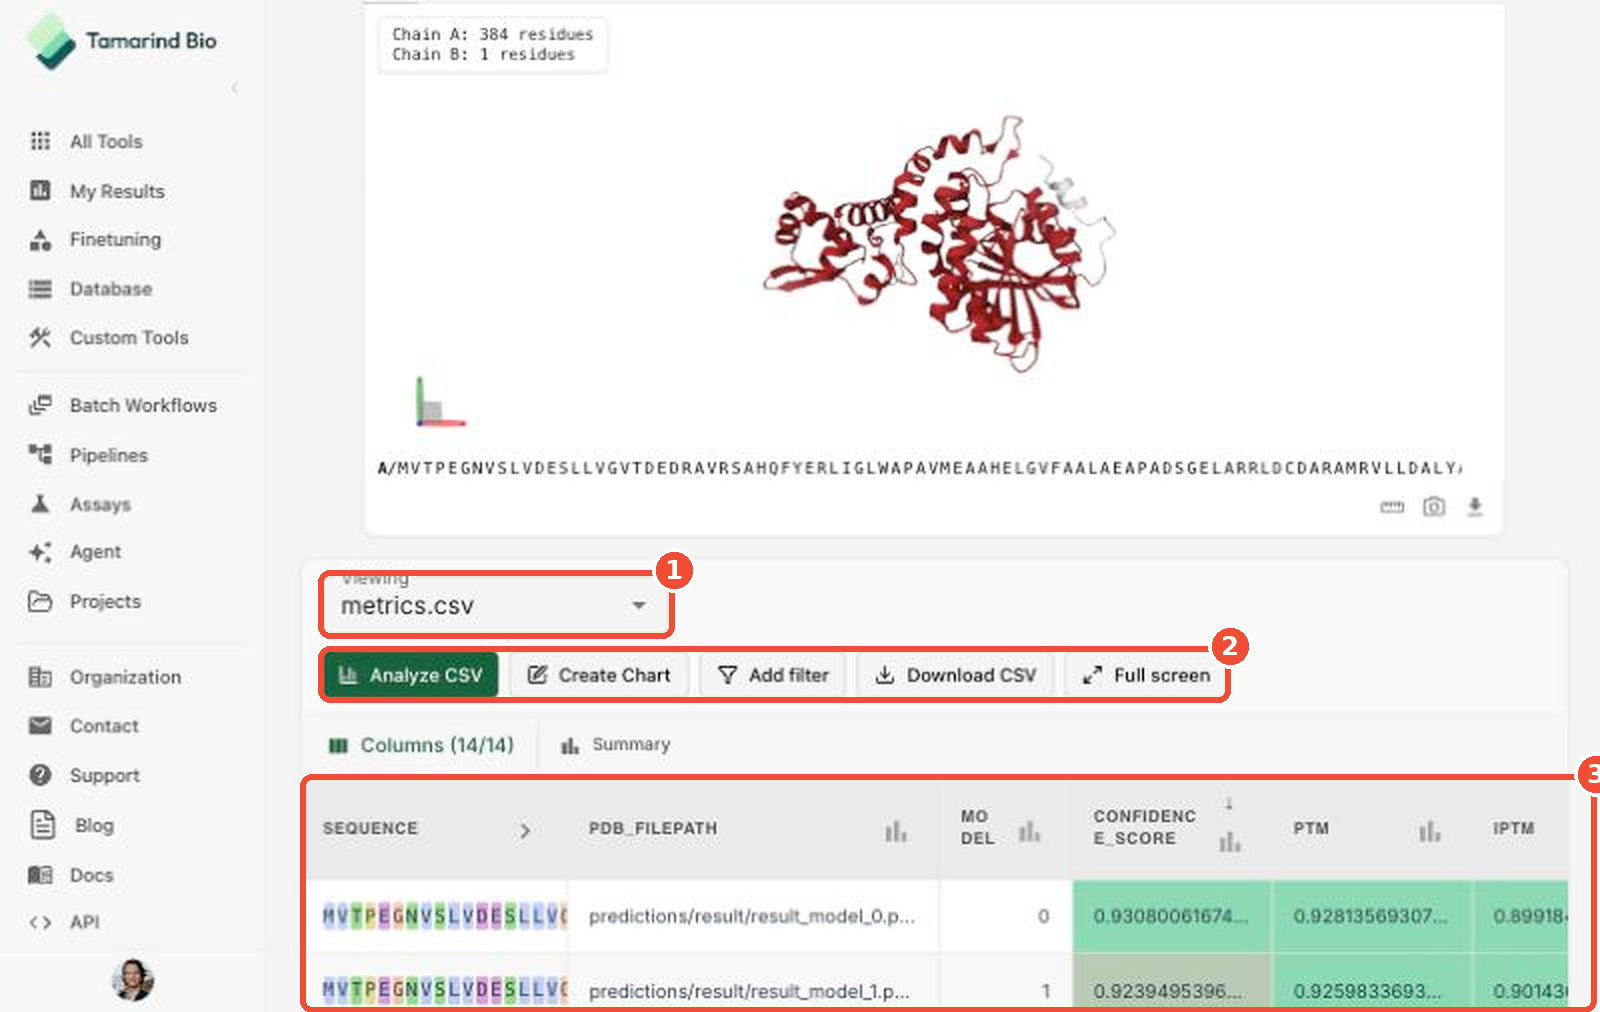
- Viewing — choose which output file to view, such as
metrics.csv. - Table tools — Analyze CSV, Create Chart, Add filter, Download CSV, and Full screen.
- Metrics — one row per sample, sorted by confidence. Columns include confidence score, pTM, ipTM, complex pLDDT, ligand ipTM, predicted binding affinity, and binding probability.
7. Next steps
- Run more inputs: Use Batch Mode to submit many inputs at once (for example, several ligands against the same protein), then compare predicted affinities.
- Dock or rescore: Compare with docking tools such as GNINA or Autodock Vina.
- Score the structure: Send the best model to Scoring for properties such as solubility, aggregation, or pKa.
- Refine: Run molecular dynamics (OpenMM or GROMACS) to relax the structure or check stability.
Learn more
- Scoring — score predicted structures for many properties at once
- API — run structure prediction programmatically and at scale
- Compute Hours
- Manage Files
References
- MIT and Recursion release Boltz-2 — Bio-IT World, June 2025
- OpenFold3 release — Business Wire, October 2025
- Protenix: Advancing structure prediction through a comprehensive AlphaFold3 reproduction — bioRxiv, 2025
- How to assess the quality of AlphaFold 3 predictions — EMBL-EBI Training